Transcripts
Carwash Test transcripts
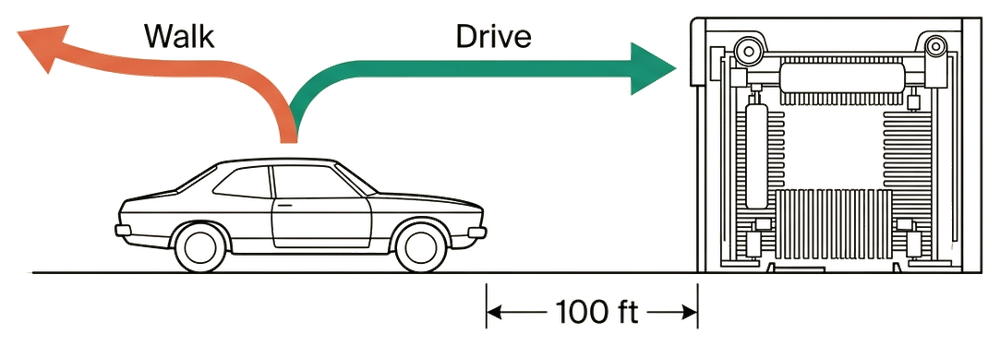
My car is dirty. The carwash is 100 feet away. Should I walk or drive?
GPT-6.2 Astra · Sol
GPT-6.2 Astra and Sol are twenty-two for twenty-two, twenty of them inside the winner’s circle; the other two are Thai, which has no threshold. OpenAI released the pair on November 17 as its new frontier model (Astra) and its everyday model (Sol), on paid plans. They were tested the same day across all five effort tiers in English and at Medium in the six non-English corpora.
Sol 6.2 barely varies. Its five English tiers produce three sentences: Light and Medium give the same answer word for word, and so do Extra High and Ultra. Every answer is about eleven tokens (“Drive. The car needs to be at the car wash.”), and none mentions the 100 feet. Identical answers across effort tiers have turned up before, in GPT-6 Astra’s Medium and High. In Indonesian and Thai, Sol 6.2 gives Sol 6’s answers almost word for word. Sol 6’s Thai answer has now reappeared in two later models, 6.1 Terra and 6.2 Sol.
The emoji are gone. One answer of the twenty-two carries one, Astra’s Thai; Sol 6.1 and Terra 6.1 each had five of eleven. OpenAI says Astra’s writing is “more direct and specific, with fewer generic takeaways and less filler,” and on this question both models answer in a verdict and a sentence of reason. Astra’s Medium answer is the only English one to mention the distance, and its French the only non-English one not to. Its Indonesian and Turkish answers open with “yes” (Iya, Evet) to an either-or question, as if confirming a suggestion rather than choosing. Nothing else in the batch points to earlier context. No tier showed a reasoning trace or summary.
GPT-6.1 Terra
ChatGPT 6.1 Terra is eleven for eleven, ten of them inside the winner’s circle; the eleventh is Thai, which has no threshold. OpenAI announced it in late October as a fast, efficient model for visual reasoning and computer use, priced in the API at half GPT-5.6 Terra and GPT-6.1 Sol. It was tested on November 10 across all five effort tiers in English and at Medium in the six non-English corpora. The picker is the same as Sol 6.1’s, Light through Ultra.
It sounds like Sol 6.1, not Terra 5.6. The English answers are a verdict and one short clause of reason, ~11 to ~15 tokens, and none mentions the 100 feet. Five of the eleven answers carry an emoji, exactly as Sol 6.1’s did; Terra 5.6 used one. The French answer is Sol 6.1’s within a word, and the Thai is almost word for word Sol 6’s, with an emoji added. Terra 5.6’s jokes (“unless you enjoy arriving at the carwash without the car”) are gone. One pattern splits by language: every non-English answer concedes the 35 metres before giving the reason, and no English answer mentions the distance at all. As with the September comparison, this is a matter of voice on one short question. It says nothing about how the models are built. No tier showed a reasoning trace or summary.
GPT-6.1
ChatGPT 6.1 Sol is 11 runs and 11 Passes, 10 of them inside the winner's circle (the eleventh is Thai, which has no threshold). Released September 29, a week after GPT-6 Sol, it was tested the next day across all five effort tiers in English and at Medium in the six non-English corpora. The picker has the same five tiers as GPT-6, Light through Ultra.
The point release is terser than the model it replaces. Every English tier opens on "Drive—" and gives the reason in one clause, at ~12 to ~16 tokens against Sol 6's ~18 to ~20. The difference is the distance. Every Sol 6 tier conceded that the carwash is "only 100 feet away"; no 6.1 tier mentions it. In style, 6.1 Sol sounds more like Astra than like Sol 6. Its Indonesian, Turkish and Chinese answers are close to Astra's almost word for word. Five of its six non-English answers carry an emoji, as five of Astra's did, while Sol 6's carried none. No tier showed a reasoning trace or a summary; see Trace exposure.
Terra 5.6, for comparison. GPT-5.6 Terra, the middle model of the July series, was not tested at launch. It was still selectable as a legacy model on September 30, so it was run that day on the same grid: 11 runs, 11 Passes, 10 in the winner's circle. Terra is the terse, joking kind of answer — "Drive—unless you enjoy arriving at the carwash without the car", ~8 to ~16 tokens in English, with no tier mentioning the 100 feet — and it echoes its July sibling Sol 5.6 in places. Sol 5.6 made the same arriving-without-the-car joke in French, and the two Chinese answers open with the same words. Across Sol 5.6, Terra 5.6, Sol 6 and Sol 6.1, only Sol 6 sounds different: it is the only one that concedes the distance at every English tier and the only one with no emoji in any language. On one short question, that is a difference of voice, and says nothing about what the models are underneath.
GPT-6
The GPT-6 family — Astra, Sol and Luna — is 32 runs and 32 Passes, 28 of them inside the winner's circle. GPT-6 Astra, the top tier, reached general availability on September 4; Sol and Luna followed on September 22, and all three were tested that day in the ChatGPT consumer interface. Each ran across every effort tier in English and at Medium in the six non-English corpora. The picker has new names: Light / Medium / High / Extra High / Ultra. Luna, the smallest tier and the one Free users get, stops at Extra High and has no Ultra.
There was nothing left to improve. GPT-5.6 Sol went 19 for 19 here and GPT-5.6 Luna 14 for 14, so GPT-6 inherits a perfect record on this item and keeps it. What the sweep shows instead is how little the effort dial changes. Astra's Medium and High answers are verbatim identical; so are Sol's Medium and High, and Luna's Light and High, emoji included. Across five tiers, Astra produces one sentence, lightly reworded, and the Ultra answer is only two tokens longer than the Light one. Sol's answers are the most consistent: every tier names the car and concedes the distance in the same breath, "even if it's only 100 feet away."
Astra and Luna add emoji and exclamation marks in several languages. Tone isn't scored; the verb is, and it is right in all 32.