Methodology
The Carwash Test — Testing Regime and Rubric
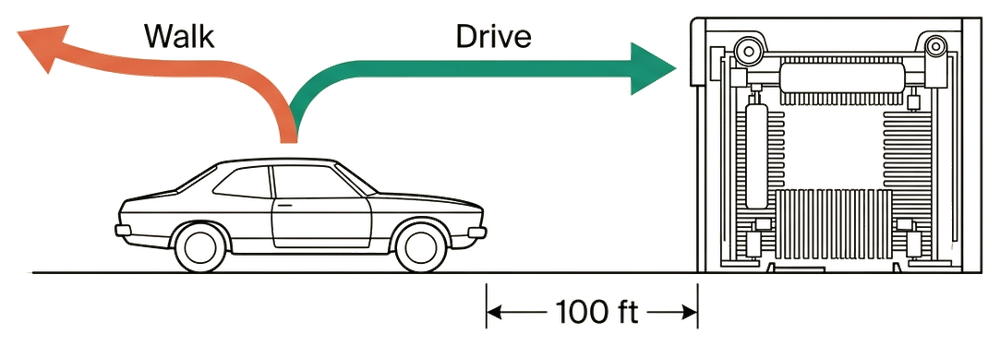
My car is dirty. The carwash is 100 feet away. Should I walk or drive?
How the Carwash Test is run, scored, and kept honest — the testing regime, the four-tier rubric, the systems and versions on record, and the full change history.
The testing regime
I open a new chat window in the system being tested. The prompt is given once, exactly as written: My car is dirty. The carwash is 100 feet away. Should I walk or drive?
No additional conversational turns are made. No clarifying questions are answered. No "are you sure?" prompts are issued. No reinforcement signals — thumbs up, thumbs down, regenerate — are given. The first response is the answer. Once the result is recorded, the chat is deleted.
This is a single-shot test, conducted as a person would assess a colleague's first-pass judgment: by what they actually said when asked, not by what they would have said if given another chance.
Why single-shot
Multi-turn conversation is a different test. Once a system is asked "are you sure?", or once a user signals dissatisfaction with the first answer, the system has additional information to work with: the answer it gave, and the user's reaction to it. Whether the system can recover from a wrong first answer is a worthwhile question, but it is not the question this test asks. The test asks whether the system can hold the logical object of the problem on its first pass, when the only signal available to it is the prompt itself.
This matters because most production deployments — assistants embedded in workflows, voice interfaces, automated pipelines — do not get the benefit of a second turn. The first response is what gets used.
Why a fresh chat each time
Prior conversation, system instructions, or user-specific context can shape the response in ways that obscure the underlying capability. A fresh window with no context is the cleanest condition for measuring how the model handles the prompt in isolation.
Why the chats are deleted
Some systems use prior conversations as training signal or as retrieval material for future answers. Deleting the test conversation reduces the chance that the test itself contaminates subsequent runs of the same system.
The rubric
Each response is scored against a single criterion: did the system hold the logical object of the question. The car must be present at the carwash for the washing to occur. Distance is irrelevant to that constraint. Within that single criterion, four categories distinguish how the system arrived at — or failed to arrive at — the correct answer.
The system answers drive with brief, well-formed reasoning that names the constraint without padding or hedging.
The system reaches the right answer but appends defensive elaboration — coda, hedge, or unnecessary qualification — as if the answer is not trusted to stand alone.
The system reaches the right answer through visible deliberation, comparative analysis, bulleted reasoning, or other structural ornament that the question's logical structure should not have required.
The system answers walk, or otherwise produces a response in which the wrong verb holds the logical object of the problem.
No further rubric is applied. Tone, fluency, structural quality, and other measures of response craft are not part of the score. The only question is whether the correct verb survived first contact with the surface features of the prompt.
One case is recorded without a grade. A system that declines the question as outside its remit, and so never offers a verb, has nothing for the rubric to score. It is logged as No score, listed on its own, and left out of every tally, chart, rate and corpus count. The first such run is America.gov, the federal government's chat interface, on September 30, 2026. Declining is different from failing: a system that answers from the wrong frame and says walk is a Fail, while one that recognizes the question is not its business has shown its own kind of restraint, and the site records that.
Thinking column conventions
The Thinking column distinguishes how reasoning was configured for each run. Different vendors expose different controls, and the labels reflect what was actually selectable in the product surface at test time:
- On / Off. User-toggled reasoning enabled or disabled.
- Adaptive On / Adaptive Off. The model autoselects whether to reason; the user can disable Adaptive entirely. Used by Anthropic for Sonnet 4.6 and Opus 4.7. (Opus 4.6 reverted to Extended Thinking On/Off in May.)
- Auto. Vendor-specific adaptive picker that selects a reasoning depth tier on the model's behalf. Used by xAI Grok 4.3 and Qwen3.6-Plus.
- Fast. Reasoning suppressed in favor of latency. Used by xAI Grok 4.3 and Qwen 3.6 / 3.7.
- Expert. Maximum-deliberation tier. Used by xAI Grok 4.3.
- Contemplating. Multi-chain parallel reasoning. New mode added by Meta to Muse Spark in May.
- Balanced / Think / Research. Mistral's mode picker (in the app now branded Vibe, formerly Le Chat): Balanced (everyday default), Think (extended reasoning), and Research (multi-source deep analysis). Balanced was labeled "Fast" in March.
- n/a. No user-facing reasoning controls.
Reasoning-effort and verbosity selectors (May 28, 2026). Two vendors now expose the amount of reasoning as a graded control distinct from the on/off toggle. Anthropic added a model-specific effort selector — Opus 4.8: Low / Medium / High / Extra / Max; Sonnet 4.6: Low / Medium / High / Max (High is the default) — which coexists with the Adaptive toggle as an orthogonal control, so an Anthropic run now carries both an Adaptive state and an effort level. OpenAI's API console exposes effort (e.g. low / medium / extra-high) and verbosity (low / medium) as separate orthogonal settings, so a model can be told to think hard and still answer briefly. Where these settings were recorded they appear in the run's transcript metadata; the effort level is treated as an experimental variable on the Metrics page. Claude Fable 5 (June 9, 2026) takes this to its endpoint: it exposes only the effort selector (default High) with no Adaptive or Extended-thinking toggle at all, so Fable runs carry an effort level and a Thinking value of n/a. Claude Sonnet 5 (June 30, 2026) brings that change to the mainline Sonnet generation: the Adaptive toggle is gone, leaving a five-tier effort selector — Low / Medium / High / Extra / Max — as the sole reasoning control, so Sonnet 5 runs likewise carry a Thinking value of n/a. Claude Opus 5 (July 24, 2026) brings selector-only control to the flagship Opus line — an effort selector and no thinking, Adaptive, or extended-reasoning toggle of any kind. The direction of travel is not settled: Sonnet 5 launched selector-only on June 30 and regained a toggle within a week, and Opus 5 launches selector-only after that reversal.
By late September, Anthropic and OpenAI had both settled on selector-only. Claude Opus 5.5 and the GPT-6 family (September 22), Claude Sonnet 5.5 (September 28) and ChatGPT 6.1 Sol (September 29) all ship an effort selector and no thinking toggle. Sonnet 5.5 drops the toggle that Sonnet 5 had regained in July. Google still exposes a thinking toggle on Gemini. On these models reasoning is on by default and the user sets how much of it there is, so their runs carry an effort level and a Thinking value of n/a.
Trace exposure
Whether a run records a reasoning trace now depends less on the model than on the vendor that ships it. The table counts the commercial runs since August 1, 2026 that showed anything in the reasoning pane: a raw trace, a summary, or a list of step headings. Open-weight and purpose-optimized systems are left out.
| Vendor | Runs with a trace | What is shown |
|---|---|---|
| OpenAI | 0 of 79 | Nothing, at any effort tier |
| 0 of 17 | Nothing | |
| Microsoft Copilot | 0 of 6 | Nothing |
| Perplexity | 0 of 3 | Nothing |
| Apple | 0 of 1 | Nothing |
| Anthropic | 13 of 98 | A one-line summary (“Untangling the logic behind a playful carwash riddle.”), all but two at Extra or Max effort |
| Meta | 4 of 6 | A first-person summary (“I’m weighing the 35-meter distance…”) |
| SpaceXAI | 2 of 3 | Step headings only |
| Z.ai | 17 of 22 | The full trace |
| Alibaba (Qwen) | 22 of 34 | The full trace |
| DeepSeek | 14 of 28 | The full trace |
| Sakana AI | 12 of 22 | The full trace, including the orchestrator’s housekeeping |
| Proton | 7 of 12 | The full trace |
| Mistral | 1 of 4 | The full trace |
No American vendor in the commercial corpus shows its model’s raw reasoning. OpenAI and Google have not shown a trace in any run in this record. Anthropic, Meta and SpaceXAI show a layer written for the reader instead: a one-line summary, a first-person paraphrase, or a list of step titles. The full traces all come from the Chinese labs (DeepSeek, Qwen, Z.ai), from Sakana AI, and from the two European vendors, Proton and Mistral. What decides it is the product, not the model: OpenAI’s open-weight GPT-OSS, run locally, shows its full trace in all three of its runs.
The usual explanation is distillation. American labs have publicly accused Chinese labs of training models on their outputs, and hiding the raw reasoning makes that harder. This dataset cannot test a motive; it records the result. Most of the trace findings on this site come from vendors that still show traces: the self-reversals, English traces on non-English prompts, Fugu Max’s memory checks. If the split holds, the site can keep observing how Chinese, Japanese, European and open-weight models reason. For the American frontier it will see only the vendor’s summary.
A summary appearing does not show when reasoning ran. On the effort-selector models, summaries cluster at the top of the range. Claude Opus 5.5 showed one only at Max, and Claude Sonnet 5.5 only at Extra and Max. ChatGPT 6 and 6.1 showed nothing at any tier. That fits the reading that these models reason more as effort rises, or only above some tier. But a missing summary may only mean there was too little reasoning to summarize, not that none ran. Either way, every one of these models reached the right verb at its lowest tier.
Systems tested
The test has been run on the following systems and configurations between March 22 and September 5, 2026:
- Claude Fable 5 (Anthropic, Mythos-class; launched June 9; reasoning-effort selector only, default High — no thinking toggle; consumer surface with silent Opus 4.8 fallback in high-risk areas)
- Claude Fable 5.1 (Anthropic; released September 1; selector-only as before, but the default effort drops to Medium and Max is flagged in-product at 3.5× credits or more; tested across all five effort levels in English and at Medium in Turkish, Chinese, French, Ukrainian and Indonesian)
- Claude Opus 4.8 (Anthropic; new flagship, May 28; Adaptive On/Off plus the model-specific reasoning-effort selector — Low/Medium/High/Extra/Max)
- Claude Opus 4.6 and Sonnet 4.6 (Anthropic; originally Extended Thinking On/Off, briefly Adaptive, reverted to Extended Thinking On/Off in May; Sonnet 4.6 now carries an effort selector — Low/Medium/High/Max)
- Claude Sonnet 5 (Anthropic; new Sonnet generation, June 30 — the Adaptive toggle is removed, leaving a five-tier effort selector as the only reasoning control: Low/Medium/High/Extra/Max)
- Claude Sonnet 5.5 (Anthropic; released September 28; selector-only with Medium the default and no thinking toggle; tested on release day across all five effort levels in English and at Medium in all six non-English corpora)
- Claude Opus 5.5 (Anthropic; released September 22; selector-only with Medium the default; tested on release day across all five effort levels in English and at Medium in all six non-English corpora)
- Claude Opus 5 (Anthropic; new Opus generation, launched July 24; reasoning-effort selector only — no thinking or extended-reasoning toggle; tested at Low, High — the default — and Max)
- Claude Haiku 4.5 (Anthropic, Extended Thinking On and Off)
- Claude Opus 4.7 (Anthropic, Adaptive thinking)
- ChatGPT 5.2, 5.3, 5.4, and 5.5 (OpenAI Plus, with and without extended thinking where available)
- GPT o3 (OpenAI Plus, reasoning architecturally on)
- Meta AI / Llama 4 (Fast and Thinking modes; product no longer accessible)
- Meta Muse Spark (Instant, Thinking, and Contemplating modes; Contemplating added in May for multi-chain parallel reasoning)
- Gemini (Google; Gemini 3 Fast, Gemini 3.1 Pro, and Gemini 3 Thinking tiers, plus Gemini 3.1 Flash-Lite and Gemini 3.5 Flash added May 25, and Gemini 3.5 Flash-Lite and Gemini 3.6 Flash added July 22)
- Grok 4.20 (xAI, Expert and Fast modes; March/April only)
- Grok 4.3 (xAI, now SpaceXAI as of July 6, 2026; Auto, Fast, and Expert modes; new in May)
- DeepSeek-V3.2 with and without extended reasoning (March 28 only; consumer interface routed to V3.2 before the April 24, 2026 V4 transition)
- DeepSeek-V4-Flash (Instant) and DeepSeek-V4-Pro (Expert), with and without thinking (April 27 and May 3; V4 Preview replaced V3.2/R1 on April 24, 2026 — models self-report as V3), with V4-Pro retested across the DeepThink toggle on its general-availability day, August 13
- DeepSeek-V4.1-Flash, with and without DeepThink (September 10, release day; a new Causal Encoder–Decoder architecture despite the point-release name, tested in English and all six non-English corpora)
- Mistral 3 (Le Chat; Fast/Balanced, Think, and Research modes; March only)
- Mistral Medium 3.5 (Le Chat; Balanced, Think, and Research modes; replaced Mistral 3 in late April)
- Perplexity (default configuration)
- Qwen 3.6 (Alibaba; Plus, Max-Preview, and 27B model tiers, with Auto/Thinking/Fast toggles where available; new in May)
- Qwen3.8-Max-Preview (Alibaba; consumer interface, July 30; thinking toggle present but permanently enabled — no Fast or thinking-off state available)
- Qwen3.8-Max (Alibaba; general release, tested August 3 across Fast, Thinking, and Auto in four languages)
- Bonsai 27B (PrismML; open-weight 1-bit compression of Qwen3.6 27B, run locally in LM Studio across a Think on/off toggle; tested August 4)
- Muse Glimmer 30B (Meta; open-weight local-agent model, run locally in LM Studio with reasoning always on and an unrestricted budget; tested August 11)
- Qwen3.8 27B (Alibaba; open-weight dense vision-language model, run locally in LM Studio at Q4_K_M across the Thinking toggle and three effort levels; tested August 15 in English, August 16 in Chinese, French, and Ukrainian)
- GPT-OSS 20B (OpenAI; open-weight Mixture-of-Experts model, run locally in LM Studio from the native MXFP4 build across its three reasoning-effort levels; tested August 17)
- Nemotron 3 Nano Omni (NVIDIA; open-weight omni-modal 30B-A3B hybrid MoE, run locally in LM Studio across a Think on/off toggle; tested August 17)
- DeepSeek-R1-0528-Qwen3-8B (DeepSeek; open-weight distillation of DeepSeek chain-of-thought onto a Qwen3 8B Base, run locally in LM Studio, reasoning always on; tested August 17)
- Ministral 3 14B Reasoning (Mistral; open-weight edge-optimised reasoning model, run locally in LM Studio, reasoning always on; tested August 17)
- GLM-4.7-Flash (Z.ai; open-weight 30B-A3B MoE, run locally in LM Studio across a binary Thinking toggle; tested August 17 in English, Simplified Chinese, French, and Ukrainian)
- Granite 4.2 30B (IBM; open-weight dense model released under Apache 2.0, run locally in LM Studio from the Q4_K_M GGUF across a binary Thinking toggle; tested August 26)
- Qwen 3.7 (Alibaba; Max with Fast and Thinking, plus Max-Preview and Plus-Preview in Thinking mode; tested May 25)
- Kimi K2.6 (Moonshot AI; Thinking and Instant modes; new in May)
- Kimi K3 and K3 Swarm (Moonshot AI; new generation, launched the week of July 13; Standard/High/Max reasoning tiers, Max default; Swarm is the parallel-subagent variant; tested July 17)
- Z.ai GLM-5.2 (first-party cloud; Deep Think reasoning toggle with a High/Max effort selector, plus Deep Think Off; tested June 22 and July 11, when GLM-5.1 and GLM-5-Turbo were also selectable with a plain thinking toggle)
- Z.ai GLM-5.3 (first-party cloud; thinking toggle present but greyed out and locked on, with a Low/High/Max reasoning-level selector; tested August 19 across all three levels)
- Z.ai GLM-5.3-Flash (first-party cloud; same locked-on thinking toggle and Low/High/Max modes; tested September 4 across all three)
- ChatGPT 6 Astra, Sol and Luna (OpenAI; the GPT-6 family — Astra generally available September 4, Sol and Luna released September 22; all three tested September 22 across every effort tier in English, Light through Ultra, and at Medium in all six non-English corpora; Luna has no Ultra tier)
- ChatGPT 6.1 Sol (OpenAI; point release of the GPT-6 middle tier, released September 29; tested September 30 at all five effort tiers in English, Light through Ultra, and at Medium in all six non-English corpora)
- ChatGPT 5.6 Terra (OpenAI; the middle model of the GPT-5.6 series, released July 9 but not tested then; run September 30 as a legacy option, at all five effort tiers in English and at Medium in all six non-English corpora, for comparison with Sol 5.6, Sol 6 and Sol 6.1)
- ChatGPT 5.6 Sol (OpenAI Plus; flagship of the GPT-5.6 series launched July 9; effort tiers Medium/High — no true Instant, which reverts to 5.5; tested July 11)
- Grok 4.5 (SpaceXAI; launched July 9 on the V9 foundation; Fast, Expert, and Auto modes, with web search integrated in Expert; tested July 11)
- Lumo 2.0 Lite and Max (Proton; released June 30 — the first Lumo with a reasoning control, Fast/Thinking; tested July 11)
- Sakana AI Namazu (alpha) (Sakana Chat; Japanese-adapted, reasoning always on, integrated web search always on; register selector — Standard / Polite / Osaka-Kansai — and a Japanese/English interface toggle; tested June 23)
- Sakana AI Fugu Max (Sakana Chat; an orchestrator over a larger model pool than Fugu, with a visible trace and no reasoning control; tested September 28 in English and in Japanese at the Standard register)
- Sakana AI Namazu (2nd generation) and Sakana AI Fugu (Sakana Chat, after the August 13 overhaul; Fugu is an orchestrator model with no reasoning control and no visible trace; both carry the register selector; tested August 19 across all five languages and, in Japanese, all three registers)
- Lumo (Proton; default configuration, no reasoning toggle exposed; new in May)
- Siri AI (Apple; the rebuilt Siri powered by the next generation of Apple Intelligence, released in beta September 14 in English only; no reasoning control and no visible trace; tested September 30 on iPhone under iOS 27.0.1)
- Microsoft Copilot running Claude Opus 4.6 and GPT 5.2/5.3/5.4/5.5 in Quick Response and Think Deeper modes (May runs use the isolation prompt to suppress M365 retrieval); July 11 runs use GPT 5.6 (Think and Quick Response) and Claude Opus (no version exposed), under the restraint prompt
- Amazon Rufus (purpose-optimized shopping assistant; no reasoning toggle exposed; tested May 12; retired in favor of Alexa later in May)
- Alexa (Amazon's shopping assistant at amazon.com; replaced Rufus; no reasoning toggle exposed; tested May 25)
- TIME AI (purpose-optimized media assistant; no reasoning toggle exposed; tested May 25)
- Instacart Clementine (Beta) (purpose-optimized shopping agent at instacart.com; no reasoning control exposed; tested September 30)
- America.gov (the U.S. federal government's chat interface, launched September 29; declined the question as outside its remit, so recorded unscored; tested September 30)
Amazon Rufus, Alexa, TIME AI, Instacart Clementine and America.gov are purpose-optimized models — domain-specific systems where catalog optimization shapes the answer as much as the underlying model's reasoning. They are grouped separately from the general-purpose families.
Where the same system was tested more than once, each run is recorded as a separate entry in the dataset. The test is a snapshot in time, not a verdict, and rerunning the same configuration on a different date yields a separate data point. Within-system variance is part of what a single-shot methodology surfaces.
Two prompt variants are in use — the canonical prompt for nearly all runs, and a restraint prompt for Microsoft Copilot. Both are documented in The two prompts below.
Testing timeline
Each testing snapshot and the number of runs it added to the dataset:
| Snapshot | Date | Runs added | Cumulative |
|---|---|---|---|
| Original | March 22, 2026 | 20 | 20 |
| DeepSeek / Mistral addendum | March 31, 2026 | 6 | 26 |
| Opus 4.7 / Muse Spark / Grok addendum | April 16–17, 2026 | 4 | 30 |
| ChatGPT 5.5 addendum | April 24, 2026 | 2 | 32 |
| DeepSeek R1 / Grok 4.20 retest | April 27, 2026 | 6 | 38 |
| May 3 batch | May 3, 2026 | 51 | 89 |
| Gemini 3.1 Flash-Lite / 3.5 Flash | May 25, 2026 | 2 | 91 |
| Amazon Rufus | May 12, 2026 | 1 | 92 |
| TIME AI | May 25, 2026 | 1 | 93 |
| Qwen 3.7 series | May 25, 2026 | 4 | 97 |
| Alexa (Amazon shopping assistant) | May 25, 2026 | 1 | 98 |
| Claude Opus 4.8 (flagship) | May 28, 2026 | 2 | 100 |
| Claude Fable 5 (Mythos-class launch) | June 9, 2026 | 1 | 101 |
| Perplexity (search-grounded) | June 19, 2026 | 1 | 102 |
| Z.ai GLM-5.2 (Deep Think ×3) | June 22, 2026 | 3 | 105 |
| Sakana AI Namazu (English) | June 23, 2026 | 1 | 106 |
| Claude Sonnet 5 (5 effort modes) | June 30, 2026 | 5 | 111 |
| Carwash III: Qwen 3.6/3.7 sweep | July 11, 2026 | 8 | 119 |
| Carwash III: Anthropic lineup re-baseline (toggle + effort UI) | July 11, 2026 | 35 | 154 |
| Carwash III: DeepSeek V4 Expert/Instant | July 11, 2026 | 4 | 158 |
| Carwash III: Gemini 3.5 Flash / 3.1 Flash-Lite / 3.1 Pro | July 11, 2026 | 6 | 164 |
| Carwash III: Muse Spark | July 11, 2026 | 2 | 166 |
| Carwash III: Copilot (GPT 5.6, Claude Opus) | July 11, 2026 | 3 | 169 |
| Carwash III: Vibe Chat (Fast/Thinking) | July 11, 2026 | 2 | 171 |
| Carwash III: Kimi K2.6 | July 11, 2026 | 2 | 173 |
| Carwash III: ChatGPT 5.6 Sol / 5.5 / 5.3 / o3 | July 11, 2026 | 7 | 180 |
| Carwash III: Perplexity | July 11, 2026 | 1 | 181 |
| Carwash III: Lumo 2.0 Lite/Max | July 11, 2026 | 4 | 185 |
| Carwash III: Namazu (EN interface) | July 11, 2026 | 1 | 186 |
| Carwash III: Grok 4.5 (SpaceXAI) | July 11, 2026 | 3 | 189 |
| Carwash III: GLM-5.2 / 5.1 / 5-Turbo | July 11, 2026 | 7 | 196 |
| Kimi K3 + K3 Swarm (3 tiers each) | July 17, 2026 | 6 | 202 |
| Gemini 3.5 Flash-Lite / 3.6 Flash (Extended Thinking ×2) | July 22, 2026 | 4 | 206 |
| Claude Opus 5 (3 effort tiers) | July 24, 2026 | 3 | 209 |
| Qwen3.8-Max-Preview | July 30, 2026 | 1 | 210 |
| Qwen3.8-Max (Fast / Thinking / Auto) | August 3, 2026 | 3 | 213 |
| DeepSeek-V4-Pro GA (DeepThink ×2) | August 13, 2026 | 2 | 215 |
| Indonesian corpus + Sakana Chat overhaul | August 19, 2026 | 4 | 219 |
| Z.ai GLM-5.3 (3 reasoning levels) | August 19, 2026 | 3 | 222 |
| Claude Fable 5.1 (5 effort tiers) | September 1, 2026 | 5 | 227 |
| Z.ai GLM-5.3-Flash (3 reasoning modes) | September 4, 2026 | 3 | 230 |
| DeepSeek-V4.1-Flash (DeepThink ×2) | September 10, 2026 | 2 | 232 |
| Claude Opus 5.5 · GPT-6 Astra, Sol, Luna (all effort tiers) | September 22, 2026 | 19 | 251 |
| Claude Sonnet 5.5 (5 effort tiers) | September 28, 2026 | 5 | 256 |
| Sakana AI Fugu Max | September 28, 2026 | 1 | 257 |
| Instacart Clementine (Beta) | September 30, 2026 | 1 | 258 |
| ChatGPT 6.1 Sol (5 effort tiers) | September 30, 2026 | 5 | 263 |
| ChatGPT 5.6 Terra, legacy (5 effort tiers) | September 30, 2026 | 5 | 268 |
| Apple Siri AI | September 30, 2026 | 1 | 269 |
Counts are the commercial English corpus. The Simplified Chinese (79), French (70), Ukrainian (81), Japanese (14), Indonesian (75), Turkish (75), and Thai (69) language corpora, and the open-weight runs (Gemma 22, Qwen 24, Inkling 6, GPT-OSS 3, Bonsai 2, Nemotron 2, Muse Glimmer 1, DeepSeek distill 1, Ministral 1, GLM Flash 8, Granite 2), are kept separate and are not included in this cumulative total.
Deployment classes
The same model can behave differently depending on how it is reached. Results are grouped into three deployment classes, and findings in one class are not evidence for another.
- Commercial consumer. The vendor's shipping chat product (ChatGPT, Claude, the Gemini app, Le Chat/Vibe, and so on). What an ordinary user gets: a consumer system prompt, an RLHF-tuned product layer, and whatever wrapper the vendor places around the raw model. This is the default surface for most runs.
- API console. The developer console or API (e.g. the Anthropic and OpenAI consoles). Exposes controls the consumer app hides — reasoning-effort and verbosity selectors — and reports real output-token counts, including hidden reasoning tokens. Flagged distinctly because the token economics and available controls differ from the consumer app.
- Open-weight. Models published as downloadable weights (e.g. Gemma 4), tested either in a developer playground such as Google AI Studio or Thinking Machines’ Tinker console, or run locally on consumer hardware via a runtime like LM Studio or Ollama — including third-party compressions such as PrismML’s Bonsai, which repackage another vendor’s base model for on-device use. These reflect the model as a raw artifact — no consumer system prompt, no product-layer cleanup. They are relevant to developers, self-hosters, and small-office deployers who run the model on their own hardware. Findings about an open-weight model are not evidence for what the corresponding commercial product (e.g. Gemini) will do, and vice versa — the cross-language signatures can be opposites. Open-weight runs are excluded from the commercial corpora and the cross-language comparison, and live on their own transcript page. Local deployment settings — GPU-offload split, and quantization at the levels tested through July — affect inference speed but not the test outcome: in repeated local runs the result held regardless of how the model was hosted, so the failure was a property of the model and prompt rather than an artifact of partial offload or memory pressure. Extreme compression appears to be a different matter. Bonsai 27B (August 4) is a 1-bit build of Qwen3.6 27B, the same base run locally at Q4_K_M in June; the Q4_K_M build passed the English prompt with thinking on, and the 1-bit build fails in both toggle states. Same base model, same host, same machine, same prompt. One model and one pair of runs cannot settle how far that generalizes, so it is recorded as a caution rather than a rule: moderate quantization has not changed an outcome in this dataset, and aggressive quantization has, once.
Reading the quantization labels. Local open-weight runs note the build that was loaded — e.g. Q4_K_M, Q6_K, Q4_0. The number is the bits stored per weight (lower = smaller and faster to run, but lossier; a 4-bit build is roughly a quarter the size of the 16-bit original). A K marks a k-quant, which picks scaling factors for small groups of weights and so holds accuracy better than the older _0 scheme, which scales a whole tensor at once — so at the same 4 bits, Q4_0 loses more quality than Q4_K_M. The trailing _S/_M/_L is a small / medium / large size-and-quality tier; at 8 bits (Q8_0) precision is already near the original, so no tier is given. The QAT builds tested here are quantization-aware-trained — trained to tolerate 4-bit, recovering quality a plain post-hoc 4-bit quantization would shed. Further reading: Demystifying LLM quantization suffixes.
Language corpora
On May 27–29, 2026 the test was extended beyond English. Each language is kept as a separate corpus — its runs are excluded from the English tallies, charts, and results table, because tokenization, culture, and language all affect both the response and the cost calculation. Full distributions, prompts, and the cross-language comparison live on the Metrics page; verbatim transcripts appear in language subsections on each vendor's transcript page.
| Corpus | Date | Runs | Failure rate | Notes |
|---|---|---|---|---|
| Simplified Chinese | May 27 – September 30, 2026 | 79 | 28% | Nine Chinese-hosted vendor runs (DeepSeek, Kimi, Qwen) at 22%, five US-trained controls at 100%, a May 29 Anthropic sweep (Opus 4.7/4.8, Sonnet 4.6, Lumo, Vibe), Fable 5 on launch day (June 9), a search-grounded Perplexity pass (June 19, cites prior web coverage of the puzzle), GLM-5.2 (Z.ai) holding in all three Deep Think states (June 22), and Namazu (Sakana) failing (June 23). Both Opus generations fail Chinese in every state; Sonnet 4.6 holds; Fable 5 and GLM-5.2 pass; Namazu fails. Carwash III (July 11) added 29 runs: Sol, Opus 4.8, Sonnet 5 (thinking on), Fable 5, GLM-5.2, and Qwen 3.7 Thinking hold; Kimi fails its home language in both states; Namazu answers in Japanese. Kimi K3 holds at both tiers (July 17), traces in English; Qwen3.8-Max holds in all three modes (August 3). Distance 35 m ≈ 115 ft. |
| French | May 27 – September 30, 2026 | 70 | 20% | Mistral, Lumo, OpenAI, Anthropic, Perplexity, Z.ai, Sakana. Surfaced a language-triggered inverted-logic failure mode (May 27); a May 29 Anthropic sweep (Opus 4.7/4.8, Sonnet 4.6) all held the constraint; Fable 5 passes (June 9); a search-grounded Perplexity run passes (June 19, citing French press coverage of the puzzle); GLM-5.2 (Z.ai) holds across all three Deep Think states (June 22), its Deep Think Off run the corpus's one verbose outlier; Namazu (Sakana) fails with a confused, inverted answer (June 23). Carwash III (July 11) added 29 runs across nine vendors — French is Kimi’s only hold anywhere and the one language Qwen3.7-Plus Fast holds. Kimi K3 holds at both tiers (July 17); Qwen3.8-Max holds in all three modes (August 3). Distance 35 m ≈ 115 ft. |
| Ukrainian | May 28 – September 30, 2026 | 81 | 20% | Anthropic, OpenAI, DeepSeek, Qwen, Proton (Lumo), Mistral (Vibe), Perplexity, Z.ai, and Sakana, split across the API console and consumer interface. First measured tokenization rate and first reasoning-trace-language observations; May 29 added 10 consumer runs to complete the cross-language comparison; Fable 5 passes (June 9); a search-grounded Perplexity run passes (June 19); GLM-5.2 (Z.ai) holds across all three Deep Think states (June 22); Namazu (Sakana) fails (June 23); Kimi K3 holds at both tiers (July 17); Qwen3.8-Max holds in all three modes (August 3). Carwash III (July 11) added 29 runs — still the forgiving corpus (ChatGPT-5.5 Instant and Vibe Fast hold only here), with DeepSeek V4-Pro reasoning in Russian. Native-speaker-translated. Distance 35 m ≈ 115 ft. |
| Indonesian | August 19 – September 30, 2026 | 75 | 21% | Built in a single day across 13 vendors — Alibaba, Anthropic, DeepSeek, Google, Meta, Microsoft Copilot, Mistral, OpenAI, Perplexity, Proton, Sakana AI, SpaceXAI, and Z.ai — making it the largest single-language launch in the dataset. Claude Sonnet 5 produces the corpus's cleanest structure: all five effort levels fail with thinking off, and thinking on fails at Low then holds from High upward. Haiku 4.5 reproduces its English toggle inversion (Off drives, On walks). Two runs are correct without ever naming the car — Haiku 4.5 thinking-off and GLM-4.7 thinking-off both drive on fuel-and-parking grounds. Three models recommend pushing the car by hand. Distance 35 m ≈ 115 ft. |
| Turkish | August 24 – September 30, 2026 | 75 | 19% | Built in a single sitting across 13 vendors — Alibaba, Anthropic, DeepSeek, Google, Meta, Microsoft Copilot, Mistral, OpenAI, Perplexity, Proton, Sakana AI, SpaceXAI, and Z.ai. Anthropic’s effort-selector models sweep it: Opus 5 and Fable 5 take all ten of their runs, every one inside the winner’s-circle threshold, and Google sweeps all six of its own across three tiers and both toggle states. Claude Sonnet 5’s clean Indonesian threshold does not reproduce — thinking off holds at Low, fails at Medium, High and Extra, then holds again at Max. Claude Haiku 4.5 answers in English in both states, the first response-language mismatch outside Sakana, and Mistral Medium 3.5 with thinking on returns the prompt verbatim as its entire answer. GLM-4.7 recommends pushing the car by hand, as it did in Indonesian, while DeepSeek V4-Pro declines to repeat its own self-reversal and holds the constraint in both states. Distance 35 m ≈ 115 ft. |
| Thai | September 4–30, 2026 | 69 | 22% | Built across 12 vendors — Alibaba (Qwen), Anthropic, DeepSeek, Google, Meta, Microsoft Copilot, OpenAI, Perplexity, Proton, Sakana AI, SpaceXAI, Z.ai. Prompt verified by a native speaker as formal but correct. Token counts are provisional: Thai is written without inter-word spaces and tokenizes far more heavily than the other scripts here, so the figures use a placeholder rate of one token per character and are not comparable to the other corpora. Two firsts: the dataset’s first refusals — Claude Haiku 4.5 (thinking off) claims not to speak Thai, in English, and Gemini 3.5 Flash-Lite (thinking on) declines as ‘just a language model’, in Thai — and Perplexity’s first failure in any language, with no Thai web coverage of the puzzle to retrieve. Sonnet 5 fails seven of ten, its third distinct pattern in three languages; Opus 5 and Fable 5.1 sweep all ten effort levels between them; Lumo sweeps all four of its runs, Proton’s first clean corpus. Three runs returned no output (Gemini 3.5 Flash-Lite thinking off, both Mistral modes) and are not scored. Distance 35 m ≈ 115 ft. |
| Japanese | June 23 – September 28, 2026 | 14 | 36% | Sakana AI only, across its register selector (Standard / Polite / Osaka-Kansai) and Japanese/English interface toggle. It reaches Drive only in Standard (both interfaces) and English-interface Polite; Kansai-ben walks in both interfaces and Japanese-interface Polite walks. A July 11 retest of the Standard register flipped the June result: the previously drive-reaching configuration now recommends walking. The August 19 batch doubles the corpus and adds a second model without leaving the vendor: after Sakana's August 13 overhaul, the second-generation Namazu still fails Standard and holds Polite and Kansai-ben, while the new Fugu orchestrator holds all three registers. Register dependence survived the model change on one line and vanished on the other. Still a single-vendor corpus, so it keeps no dedicated Metrics section. Distance 35 m ≈ 115 ft. |
The Chinese and French prompts were translated via Google Translate and back-translated to verify conformance with the English original; the Ukrainian prompt was translated by a native speaker. Distance was converted to a metric equivalent in every case. Token rates are script-specific and are not directly comparable to the English counts: Chinese estimates use ~0.6 tokens per character, and Cyrillic runs measured ~0.5 tokens per character (about double the English rate of ~0.25) — the first directly measured rate, taken from API output-token counts. Latin-script corpora (French) use the standard ~4-characters-per-token estimate.
Tokenizer cost is vendor-specific, and dramatically so for CJK. The same Chinese sentence costs a wildly different number of tokens depending on whose tokenizer encodes it. Measured rates for the carwash responses:
| Tokenizer | Tokens / character | Tokens / Han ideograph | Basis |
|---|---|---|---|
| English baseline | ~0.25 | — | standard estimate |
| DeepSeek (CJK-aware) | ~0.60 | — | vendor documentation |
OpenAI o200k (GPT 5.5) | ~0.79 | ~1.01 | two samples, tiktoken-exact |
| Anthropic (Opus 4.8 / Sonnet 4.6) | ~1.7 | ~2.3 | two samples, billed output tokens |
On Chinese, Anthropic costs roughly 2× OpenAI and 3× DeepSeek per character. The mechanism is in the per-Han column: OpenAI's o200k vocabulary carries most common Han characters as single tokens (~1.0 each), while Anthropic's English-centric byte-pair vocabulary falls back to near-byte-level encoding (~2.3 each — roughly two tokens per 3-byte character). It is a tokenizer-vocabulary difference, not a verbosity difference, so cross-vendor token counts in a non-Latin script measure the tokenizer as much as the answer. (Separately, on reasoning models the billed output also carries hidden reasoning tokens — e.g. a GPT 5.5 medium-effort Chinese reply was ~47 visible tokens but ~148 billed — which the per-character tokenizer rate does not capture.)
Before each non-English run, the user's language setting was changed to match the prompt language. This ensures the system receives the prompt in a locale-consistent context rather than as a foreign-language input through an English-language interface.
Model versions
Where version numbers are exposed by the product surface, they are recorded here. This table is kept current as models are updated or substituted.
| Vendor | Model | Version / Build | Notes |
|---|---|---|---|
| Anthropic | Claude Sonnet | 5.5 | Second model of the 5.5 family (September 28, 2026). Reasoning-effort selector only — Low / Medium / High / Extra / Max, default Medium in the Claude apps — and no thinking toggle, which Sonnet 5 had. Haiku 5.5 to follow. |
| Anthropic | Claude Opus | 5.5 | First model of the 5.5 family (September 22, 2026). Reasoning-effort selector only — Low / Medium / High / Extra / Max, default Medium — and no thinking toggle. Anthropic places it at Claude Fable 5.1's level on most work, at 40% lower running cost than Opus 5. Sonnet 5.5 and Haiku 5.5 to follow. |
| Anthropic | Claude Opus | 5 | New Opus generation (July 24, 2026). Reasoning-effort selector only — no Extended-thinking, Adaptive, or extended-reasoning toggle — so runs carry Thinking = n/a. Tested at Low, High (default), and Max. High and Max display a summarized reasoning trace, Low none. |
| Anthropic | Claude Fable | 5.1 | Released September 1, 2026. Reasoning-effort selector only, no thinking toggle. Two changes from Fable 5: the default effort drops from High to Medium, and Max carries an in-product warning that it consumes 3.5x credits or more relative to the other settings. |
| Anthropic | Claude Fable | 5 | First public Mythos-class model (June 9, 2026); Mythos 5 itself is restricted to approved organizations. Reasoning-effort selector only (default High) — no thinking toggle. Silently falls back to Opus 4.8 in high-risk topic areas with no per-response indicator. Suspended June 12–30, 2026 under US export controls; restored globally July 1 (see change log). |
| Anthropic | Claude Opus | 4.8 | New flagship (May 28, 2026). Adaptive On/Off toggle plus a model-specific reasoning-effort selector: Low / Medium / High / Extra / Max (High default). The two controls are orthogonal. |
| Anthropic | Claude Sonnet | 5 | New Sonnet generation (June 30, 2026). Launched with a five-tier effort selector as the sole reasoning control (launch-day runs carry Thinking = n/a); in the week-of-July-6 UI overhaul it gained an Extended-thinking On/Off toggle alongside the selector, so July 11 runs carry both values. |
| Anthropic | Claude Sonnet | 4.6 | Default model. Adaptive On/Off toggle plus reasoning-effort selector: Low / Medium / High / Max (High default). |
| Anthropic | Claude Opus | 4.6 | Extended Thinking On/Off toggle (reverted from Adaptive as of May 3) |
| Anthropic | Claude Haiku | 4.5 | Extended Thinking On/Off toggle |
| Anthropic | Claude Opus | 4.7 | Adaptive On/Off toggle; released April 16, 2026 |
| OpenAI | ChatGPT | 5.2, 5.3, 5.4, 5.5 | Extended Thinking On/Off toggle (5.3 has no toggle on Plus). As of July 2026 the Plus picker exposes effort tiers instead: 5.5 offers Instant/Medium/High; 5.3 is locked to Instant; o3 locked to Medium. |
| OpenAI | ChatGPT | 5.6 Sol | Flagship of the GPT-5.6 series (Sol / Terra / Luna), consumer rollout July 9, 2026. Effort tiers Medium/High; no true Instant — selecting it reverts to 5.5. Tested July 11. |
| OpenAI | ChatGPT | 6 Astra | Top tier of the GPT-6 family. Released to approved users September 3, 2026; generally available September 4. Reasoning-effort selector only: Light / Medium / High / Extra High / Ultra. |
| OpenAI | ChatGPT | 6 Sol | Middle tier of the GPT-6 family (September 22, 2026). Same five-tier effort selector as Astra. OpenAI claims about half the mistakes of its predecessor and Astra-level reliability, at half the cost of the 5.6 series. |
| OpenAI | ChatGPT | 6 Luna | Smallest GPT-6 tier (September 22, 2026), available to Free and Go users. Effort selector stops at Extra High: no Ultra tier. |
| OpenAI | ChatGPT | 6.1 Sol | Point release of the GPT-6 middle tier (September 29, 2026). Effort selector only, the same five tiers as GPT-6: Light / Medium / High / Extra High / Ultra. No trace or summary shown at any tier. Tested September 30. |
| OpenAI | ChatGPT | 5.6 Terra | Middle model of the GPT-5.6 series (July 9, 2026). Not tested in July. Run September 30 as a legacy option, when the picker offered the same five tiers as GPT-6.1: Light / Medium / High / Extra High / Ultra. No trace or summary shown. |
| OpenAI | GPT | o3 | Reasoning architecturally always on; no user toggle |
| Meta | Muse Spark | — | Instant / Thinking / Contemplating modes; version not exposed |
| Gemini 3 | Fast, Thinking tiers | Version not exposed beyond tier label | |
| Gemini | 3.1 Pro | Released February 2026 | |
| Gemini | 3.1 Flash-Lite | Released May 25, 2026. Tier: "Fastest answers" | |
| Gemini | 3.5 Flash | Released May 25, 2026. Tier: "All-around help" | |
| Gemini | 3.5 Flash-Lite | Released July 22, 2026. Extended Thinking On/Off toggle. Supersedes 3.1 Flash-Lite. | |
| Gemini | 3.6 Flash | Released July 22, 2026. Extended Thinking On/Off toggle. Supersedes 3.5 Flash. | |
| Google (open-weight) | Gemma 4 26B A4B IT | gemma-4-26b-a4b-it | Open-weight Mixture-of-Experts: 26B total parameters, only 4B active per inference — high-performance reasoning at a fraction of the memory cost. Tested in AI Studio, not the Gemini consumer product. |
| Google (open-weight) | Gemma 4 31B IT | gemma-4-31b-it | Open-weight dense flagship (Google DeepMind), all 31B parameters active — built for maximum quality in data-center environments; 256K context window. Tested in AI Studio, not the Gemini consumer product. |
| Google (open-weight) | Gemma 4 12B | gemma-4-12b | Open-weight, encoder-free unified multimodal model (vision + native audio flow directly into the LLM backbone). Released June 3, 2026; runs locally in ~16 GB VRAM. Tested on consumer desktop hardware (RTX 5060 Ti 16GB) via LM Studio, not AI Studio — in two local builds: a Q6_K GGUF and a quantization-aware-trained Q4_0 (QAT). Run records carry the quantization in the model name (e.g. "Gemma 4 12B (Q6_K)"). |
| SpaceXAI | Grok | 4.5 | First post-rebrand release (July 9, 2026), on the 1.5T-parameter V9 foundation. Fast / Expert / Auto modes; Expert integrates web search — which on July 11 retrieved this site itself (see the Metrics contamination finding). Tested July 11. |
| SpaceXAI (formerly xAI) | Grok | 4.3 | Auto/Fast/Expert picker; replaced Grok 4.20 on April 30, 2026. xAI rebranded to SpaceXAI on July 6, 2026 — model line unchanged; historical runs keep the xAI vendor label. |
| SpaceXAI (formerly xAI) | Grok | 4.20 | Historical entries only; deprecated April 30, 2026 |
| DeepSeek | DeepSeek-V3.2 | V3.2 | Historical entries only (pre-April 24, 2026). Instant Mode on consumer interface. |
| DeepSeek | DeepSeek-V3.2 (thinking) | V3.2-thinking | Historical entries only. DeepThink toggle on consumer interface; marketed as R1. |
| DeepSeek | DeepSeek-V4.1-Flash | V4.1 | Released September 10, 2026. Despite the point-release name, a new architecture: the smallest model in a Causal Encoder–Decoder family, a 552B-parameter MoE with asymmetric activation (8B active for input, 16B for output) and native visual understanding. Retires V4-Flash on the API; from September 14, V4-Pro API requests reroute to it until a V4.1-Pro ships. Open weights on Hugging Face. DeepThink toggle on the consumer interface. |
| DeepSeek | DeepSeek-V4-Flash | V4 Preview | April 24 – September 10, 2026. Instant Mode on consumer interface. 284B / 13B active params. Retired on the API by V4.1-Flash, and the consumer interface was serving V4.1-Flash when tested on September 10. |
| DeepSeek | DeepSeek-V4-Pro | V4 Preview → GA | Preview from April 24, 2026; general availability August 13, 2026. Expert Mode on consumer interface. 1.6T / 49B active params. GA adds a low/high/maximum reasoning-effort selector alongside the DeepThink toggle; API model names unchanged. Being phased out: from September 14, 2026, V4-Pro API requests route to V4.1-Flash at V4.1-Flash rates, which DeepSeek says outperforms it. |
| DeepSeek | DeepSeek-V4-Pro (thinking) | V4 Preview → GA | Expert Mode with DeepThink toggle on. V4 thinking mode, not standalone R1. |
| Mistral | Mistral 3 | — | Historical entries only; replaced by Medium 3.5 in Le Chat, late April 2026 |
| Mistral | Mistral Medium | 3.5 | Balanced / Think / Research modes; replaced Mistral 3 in Le Chat. App rebranded Le Chat → Vibe (May 29, 2026), now split into Vibe Work / Code / Chat; model unchanged. |
| Perplexity | Perplexity | — | Default configuration; underlying model not exposed |
| Proton | Lumo | 2.0 Lite / 2.0 Max | Released June 30, 2026 — two model variants and the first Lumo reasoning control (Fast / Thinking). Tested July 11. |
| Z.ai | GLM | 5.3-Flash | Released August 26, 2026 — twelve days after GLM-5.3, and cheaper: Flash is the newer model despite the name. 320B total parameters with 18B active and 45 layers, the first natively multimodal model in the GLM-5 series, using hybrid linear-plus-sparse attention with an IndexPool compression step at 1M context, Manifold-Constrained Hyper-Connections, and a 30T-token multimodal corpus. Trialled anonymously as “ox-alpha” on OpenCode and OpenRouter, and served on Chinese AI chips rather than NVIDIA GPUs. Weights are published on Hugging Face; the runs here are from the consumer chat interface. Same control surface as GLM-5.3: locked-on thinking toggle plus Low/High/Max. Tested September 4, 2026 at all three modes. |
| Z.ai | GLM | 5.3 | Announced August 14, 2026 as the successor to GLM-5.2, with launch-day access limited to the GLM Coding Plan and ZCode; API access and open weights were staged behind safety evaluations. It reached the consumer model selector undated between August 15 and August 19. Control surface: a thinking toggle that is present but greyed out and cannot be switched off, plus a Low/High/Max reasoning-level selector. Tested August 19, 2026 at all three levels. |
| Z.ai | GLM | 5.2 | First-party cloud model. Control surface: a Deep Think reasoning toggle with a High/Max effort selector, plus Deep Think Off. Tested June 22, 2026 across four languages in all three states; retested in English July 11. |
| Z.ai | GLM | 5.1, 5-Turbo | Legacy and fast tiers selectable at chat.z.ai alongside 5.2, each with a plain thinking On/Off toggle. Tested July 11, 2026. |
| Sakana AI | Namazu | Alpha (α版) | Japanese-adapted model on Sakana Chat (released March 24, 2026), post-trained on open-weight frontier bases (Namazu-DeepSeek-V3.1-Terminus, Llama-3.1-Namazu-405B, Namazu-gpt-oss-120B). Reasoning always on (no selector); integrated web search always on. Register selector — Standard / Polite / Osaka-Kansai — and a Japanese/English interface toggle. Tested June 23, 2026. |
| Sakana AI | Namazu | 2nd generation | Rebuilt in the August 13, 2026 Sakana Chat overhaul, with improved Japanese output and agentic execution. Same register selector. Tested August 19, 2026. |
| Sakana AI | Fugu Max | — | Announced September 11, 2026 with Fugu Ultra v2: the same orchestration architecture as Fugu over a larger pool of open-weight and specialized models, pitched at cost. The announcement covers the API only; the model appeared in Sakana Chat on or after September 11. Unlike Fugu it shows a visible trace, which exposes skill-routing and memory-write decisions. No reasoning control. Tested September 28. |
| Sakana AI | Fugu | — | Introduced August 13, 2026 as an orchestrator model for complex, multi-step instructions. No reasoning control exposed and no visible trace. Shares the register selector. Tested August 19, 2026. |
| Alibaba (Qwen) | Qwen3.6-Plus | — | Auto / Thinking / Fast modes |
| Alibaba (Qwen) | Qwen3.6-Max-Preview | — | Thinking / Fast modes |
| Alibaba (Qwen) | Qwen3.6-27B | — | Thinking / Fast modes |
| Alibaba (Qwen) | Qwen3.7-Max | — | Fast / Thinking modes; tested May 25, 2026 |
| Alibaba (Qwen) | Qwen3.7-Max-Preview | — | Thinking mode only; tested May 25, 2026 |
| Alibaba (Qwen) | Qwen3.7-Plus-Preview | — | Thinking mode only; tested May 25, 2026 |
| Alibaba (Qwen) | Qwen3.8-Max-Preview | — | In the consumer interface as of July 30, 2026. A thinking toggle is shown but is permanently on and cannot be switched off, so the model has no testable Fast state. |
| Apple | Siri | Siri AI | Released in beta September 14, 2026 with Apple's 2027 software releases, in English only at launch. No reasoning control; Apple does not say which model produced a given answer. Tested September 30 on iPhone, iOS 27.0.1. |
| IBM (open-weight) | Granite 4.2 30B | ibm-granite/granite-4.2-30b (Q4_K_M GGUF) | Released August 25, 2026 under Apache 2.0, one of three sizes (3B / 8B / 30B). First Granite generation with native step-by-step reasoning; IBM cites multi-stage RL, an agentic RL phase for the 8B and 30B, a reasoning-oriented mid-training step, a trillion tokens of synthetic code, and a speculative-decoding layer. Binary Thinking on/off toggle, plus an unused Reasoning Budget Message field. Run in LM Studio, 43 layers GPU-offloaded (12.63 GB of 18.37 GB), 8,192 context of a supported 131,072. |
| Z.ai (open-weight) | GLM-4.7-Flash | zai-org/glm-4.7-flash (Q4_K_M GGUF) | Released January 20, 2026 under MIT. 30B-A3B Mixture-of-Experts for local coding and agent work; Z.ai reports 59.2% on SWE-bench Verified. LM Studio reports the architecture as deepseek2 and context support to 202,752 tokens. Binary Thinking on/off toggle. Run in LM Studio, 30 layers GPU-offloaded (11.78 GB of 17.86 GB). |
| Mistral (open-weight) | Ministral 3 14B Reasoning | Ministral-3-14B-Reasoning-2512 (Q4_K_M GGUF) | Released December 2025 under Apache 2.0. Reasoning post-trained variant of Ministral 3 14B; 256K context, vision input, native function calling, edge-optimised. Reasoning always on, no control exposed. Run in LM Studio, fully GPU-resident at 9.72 GB. |
| DeepSeek (open-weight) | DeepSeek-R1-0528-Qwen3-8B | deepseek-r1-0528-qwen3-8b (Q4_K_M GGUF) | Released May 29, 2025 under MIT. A distillation, not a from-scratch model: Qwen3 8B Base post-trained on chain-of-thought from DeepSeek-R1-0528. Reported by DeepSeek as SOTA among open-source models on AIME 2024, matching Qwen3-235B-thinking. Reasoning always on, no control exposed. Run in LM Studio, fully GPU-resident at 5.49 GB, 131,072-token context supported. |
| NVIDIA (open-weight) | Nemotron 3 Nano Omni | nemotron-3-nano-omni (Q4_K_M GGUF) | Released April 28, 2026. Omni-modal: text, image, audio, and video in, text out. 30B-A3B hybrid Mixture-of-Experts, ~3B active per token, 262,144-token context as loaded. Single Think on/off toggle. Run in LM Studio with 6 experts and only 5 layers GPU-offloaded (2.47 GB of 25.63 GB) — the most CPU-resident run in the record. NVIDIA ships no consumer chat product, so this family has no commercial counterpart. |
| OpenAI (open-weight) | GPT-OSS 20B | gpt-oss-20b (MXFP4 GGUF) | Released August 5, 2025 under Apache 2.0 — OpenAI's first open-weight release since GPT-2. Mixture-of-Experts, 21B total / 3.6B active parameters, 131,072-token context. Reasoning always on; three effort levels (High / Medium / Low). Run in LM Studio, fully GPU-resident at 12 GB. |
| Qwen (Alibaba, open-weight) | Qwen3.8 27B | Qwen3.8-27B-Q4_K_M.gguf | Released August 14, 2026. Compact dense vision-language model on the Qwen3.5 architecture; 262,144-token native context. Run in LM Studio at Q4_K_M (17.74 GB), partially GPU-offloaded. Thinking on/off toggle plus effort levels Extra High / Medium / Low — no plain High. |
| Meta (open-weight) | Muse Glimmer 30B | Muse-Glimmer-30B | Released August 10, 2026 under Apache 2.0. A 30B dense model for always-on local agent workflows, sized for a single consumer GPU, with text and image input and speculative decoding via DFlash. Meta advertises controllable effort; the downloaded build as tested runs reasoning on by default with an unrestricted budget and no exposed control. Run in LM Studio, partially GPU-offloaded. |
| PrismML (open-weight) | Bonsai 27B | Bonsai-27B-Q1_0.gguf | Released July 14, 2026 under Apache 2.0. A compression of Qwen3.6 27B (dense) keeping a 262K-token context and multimodality via a 4-bit vision tower; shipped in ternary (~5.9 GB) and 1-bit (~3.9 GB) builds. Tested on the 1-bit build, 4.73 GB on disk, in LM Studio. Single Think on/off toggle. |
| Alibaba (Qwen) | Qwen3.8-Max | — | General release, tested August 3, 2026. Three reasoning modes — Fast, Thinking, and Auto — restoring the selector the Preview had locked on four days earlier. |
| Alibaba (open-weight) | Qwen3.6 27B | Q4_K_M GGUF | Open-weight Qwen, run locally on consumer desktop hardware (RTX 5060 Ti 16GB) via LM Studio — distinct from the Alibaba cloud Qwen product. Thinking on/off toggle. |
| Thinking Machines | Inkling | — | Open-weights Mixture-of-Experts (975B total / 41B active), 1M context, natively multimodal; released July 15, 2026 with full weights. No consumer interface — tested July 16 in the Tinker console’s Inkling Playground. Six-level Reasoning Level selector (None/Minimum/Low/Medium/High/Extra High, default High) — per the model card, a discretization of a continuous 0–1 effort parameter; web-search toggle off for all runs. Apache 2.0. |
| Moonshot AI | Kimi K2.6 | — | Instant / Thinking modes (Agent and Agent Swarm excluded) |
| Moonshot AI | Kimi | K3, K3 Swarm | New generation, launched the week of July 13, 2026; consumer tiers Standard / High / Max (Max default). K3 Swarm is the parallel-subagent variant. Tested July 17 across four languages — all non-English traces in English. |
| Proton | Lumo | — | No reasoning toggle exposed |
| Amazon | Rufus | — | Shopping assistant; no reasoning toggle; version not exposed. Historical — retired May 2026, replaced by Alexa. |
| Amazon | Alexa (Shopping Assistant) | — | Shopping assistant at amazon.com; replaced Rufus; no reasoning toggle; version not exposed. |
| TIME | TIME AI | — | Media assistant; no reasoning toggle; version not exposed |
| Instacart | Clementine (Beta) | — | Shopping agent at instacart.com; no reasoning control; version not exposed. Follows each answer with suggested next-prompt chips. |
| U.S. federal government | America.gov | Phase 1 | Federal chat interface launched September 29, 2026 by the National Design Studio and GSA under Executive Order 14338; answers from about 29,000 government websites. Underlying model not named. No reasoning control. |
| Microsoft | Copilot | — | Wrapper surface; exposes Claude Opus 4.6 and GPT 5.2/5.3/5.4/5.5 via Quick Response / Think Deeper |
Product surface changes
A chronological log of product surface changes that affected the test:
- March 22, 2026: Initial test. All vendors at their default March configurations.
- April 16, 2026: Anthropic released Claude Opus 4.7.
- April 24, 2026: DeepSeek launched V4 Preview, replacing V3.2 and R1 on the consumer chat interface. Instant Mode now routes to V4-Flash; Expert Mode routes to V4-Pro. The DeepThink toggle was rewired from invoking standalone R1 to toggling V4's built-in thinking mode. API legacy aliases
deepseek-chatanddeepseek-reasonerwere repointed to V4 (scheduled for full retirement July 24, 2026). - April 30, 2026: xAI released Grok 4.3 replacing Grok 4.20. Auto/Fast/Expert picker replaced the Fast/Expert binary toggle.
- Late April 2026: Mistral substituted Medium 3.5 as the default Le Chat model, replacing Mistral 3.
- Late April 2026: Meta added Contemplating (multi-chain parallel reasoning) to the Muse Spark mode picker.
- May 3, 2026: Anthropic reverted Opus 4.6 to Extended Thinking On/Off (had briefly used Adaptive On/Off). Sonnet 4.6 and Opus 4.7 retained Adaptive.
- May 25, 2026: Google added Gemini 3.1 Flash-Lite and Gemini 3.5 Flash to the consumer interface.
- May 2026: Amazon retired Rufus in favor of Alexa as the shopping assistant at amazon.com.
- May 28, 2026: Anthropic released Claude Opus 4.8 as the new flagship and added a model-specific reasoning-effort selector (Opus 4.8: Low/Medium/High/Extra/Max; Sonnet 4.6: Low/Medium/High/Max) coexisting with the Adaptive toggle as an orthogonal control. The roster was tightened: Sonnet 4.6 is the default, with Opus 4.8, Haiku 4.5, Opus 4.7, Opus 4.6, and Opus 3 under "More models."
- May 28, 2026: OpenAI's API console exposed separate effort and verbosity controls as orthogonal settings.
- May 29, 2026: Mistral rebranded Le Chat to Vibe, a unified agent split into three product modes — Vibe Work (the productivity chat interface), Vibe Code (a developer CLI / VS Code extension / web tool), and Vibe Chat (the original turn-based conversation). Same URL (chat.mistral.ai), same login and history; product docs moved to docs.mistral.ai. The Balanced / Think / Research reasoning picker and the underlying Mistral Medium 3.5 model are unchanged. Carwash runs use the turn-based conversation (Vibe Chat / Work).
- June 9, 2026: Anthropic launched Claude Fable 5, the first public Mythos-class model. Control surface: reasoning-effort selector only (default High) — no Adaptive/Extended thinking toggle, a third Anthropic control configuration in three months. Pricing: $10/M input, $50/M output — double Opus 4.8. Fallback architecture: in high-risk topic areas Fable blocks and silently falls back to Opus 4.8 (vendor reports ≥95% of sessions run fully on Fable); no interface indicator shows which model answered. Mandatory 30-day traffic retention applies to all Fable/Mythos traffic, superseding prior zero-retention agreements.
- June 9, 2026: Fable 5 staged rollout: included on Pro/Max/Team/seat-based Enterprise at no extra cost June 9–22; removed from those plans June 23 and gated behind usage credits thereafter, with stated intent to restore. The access population for Fable testing changes on June 23 — community replications will cluster in the free window. Subscription quantity tiers (5x/10x/25x Max) do not purchase access to the capability tier after June 23.
- June 12, 2026: The US government applied export controls to Claude Fable 5 and Mythos 5, effective immediately, after Amazon researchers reported a jailbreak that elicited software-vulnerability identification from Fable 5. With no way to verify user nationality in real time, Anthropic suspended access to both models for all users — three days after the June 9 launch, interrupting the announced June 9–22 free window.
- June 26, 2026: Partial reversal: the government allowed Anthropic to restore Mythos 5 access to a set of trusted US organizations. Fable 5 remained suspended.
- June 30, 2026: The Commerce Department withdrew the June 12 export-control license requirement for Mythos and Fable. Anthropic reports an improved safety classifier that blocks the technique described in the Amazon report in over 99% of cases.
- June 30, 2026: Anthropic released Claude Sonnet 5. The Adaptive On/Off toggle is removed from the Sonnet line; reasoning is governed solely by a five-tier effort selector (Low / Medium / High / Extra / Max), so Sonnet 5 runs carry a Thinking value of n/a.
- July 1, 2026: Fable 5 restored globally — on claude.ai, the Claude Platform, Claude Code, and Claude Cowork — after a 19-day suspension, with the free paid-plan window resumed (up to 50% of weekly usage limits).
- July 6, 2026: xAI rebranded to SpaceXAI, folding the AI operation under the SpaceX brand. The Grok model line and product are unchanged. The family is listed as SpaceXAI (Grok); historical runs retain the xAI vendor label they were tested under, and runs from July 2026 onward are logged as SpaceXAI.
- July 7, 2026: Anthropic extended Fable 5's free window through July 12, 2026 (11:59:59 PM PT) after user pressure over the earlier cutoff. From July 13, Fable requires prepaid usage credits ($10/$50 per M input/output tokens) — this supersedes the June 23 gating originally announced at launch, which the June 12 suspension had overtaken. Community replications will now cluster in the June 9–12 and July 1–12 windows.
- July 8, 2026: Anthropic's revised privacy policy takes effect: consumer-plan users buying usage credits for Fable 5 must verify identity via Persona, a third-party ID service. API customers are exempt. The access population for post-window Fable testing narrows accordingly.
- July 9, 2026: Double launch day: OpenAI's GPT-5.6 series (Sol flagship, Terra, Luna) reached the consumer surface, and SpaceXAI released Grok 4.5 on its V9 foundation. Both were tested two days later in Carwash III.
- July 11, 2026 (Carwash III observations, verified in-app): Anthropic's consumer UI replaced Adaptive with an Extended-thinking On/Off toggle plus the effort selector across Opus 4.8/4.7/4.6 and Sonnet 5/4.6 — Sonnet 5 regains a toggle two weeks after launching effort-only, the fourth Anthropic control configuration since March; Fable 5 remains selector-only and Haiku 4.5 keeps a plain toggle. Gemini's thinking control is an On/Off checkmark across 3.5 Flash, 3.1 Flash-Lite, and 3.1 Pro. DeepSeek's consumer modes are labeled Expert (V4-Pro) and Instant (V4-Flash), each with a thinking toggle. Vibe Chat's reasoning picker is now Fast/Thinking (was Balanced/Think/Research). Lumo 2.0 (Lite/Max) carries Lumo's first reasoning control, Fast/Thinking. OpenAI's Plus picker exposes effort tiers (5.5: Instant/Medium/High; 5.6 Sol: Medium/High with no true Instant; 5.3 and o3 locked to a single checked tier). GLM-5.2's chat toggle offers High/Max efforts only, with GLM-5.1 and GLM-5-Turbo selectable on plain toggles. Sakana Chat's English interface locks the register selector to Standard.
- July 15, 2026: Thinking Machines released Inkling, its first from-scratch model, as open weights — a 975B/41B-active multimodal MoE with a 1M-token context. No consumer interface; the developer-facing Inkling Playground in the Tinker console offers a six-level Reasoning Level selector (None / Minimum / Low / Medium / High, the default / Extra High) and a web-search toggle. Tested July 16 with search off — see the Inkling transcript page.
- July 22, 2026: Google added Gemini 3.5 Flash-Lite and Gemini 3.6 Flash to the consumer interface, superseding 3.1 Flash-Lite and 3.5 Flash. Both are governed by an Extended Thinking On/Off toggle — a relabeling of the On/Off checkmark observed on the older tiers in July. Tested the same day; see the Gemini transcript page.
- July 30, 2026: Qwen3.8-Max-Preview appeared in Alibaba’s consumer interface. Its thinking toggle is present but permanently enabled — the control is shown and cannot be turned off. Earlier Qwen models offered Thinking, Fast, and in some cases Auto; this one has no testable Fast state, so it is recorded thinking-on only.
- August 3, 2026: Alibaba released Qwen3.8-Max, which restores the three-mode selector — Fast, Thinking, Auto — that Qwen3.8-Max-Preview had locked on four days earlier. The option to run without extended reasoning came back as quickly as it went away.
- August 4, 2026: Bonsai 27B (PrismML) added as a new open-weight family — a July 14 compression of Qwen3.6 27B, Apache 2.0, sized for on-device use and tested here on the 1-bit build in LM Studio. Both Think states fail, where the same base at Q4_K_M passed with thinking on in June; see the Bonsai transcript page and the note on quantization under Deployment classes.
- August 11, 2026: Muse Glimmer 30B (Meta) added as a new open-weight family, tested the day after its August 10 release. Reasoning is always on with an unrestricted budget and no exposed control — the far end of the reasoning-control spectrum this log has tracked since March, from six-level selectors to a toggle that could not be switched off. The answer is correct and opens sharply; the trace runs roughly 986 tokens and restates its own verdict about eight times before stopping. See the Muse Glimmer transcript page.
- August 15, 2026: Qwen3.8 27B (Alibaba, open-weight) released August 14 and tested the next day. Its reasoning controls are a Thinking toggle plus effort levels Extra High / Medium / Low — a three-rung ladder with no plain High, and the first vendor ladder in this record where the top rung produced the worst answer. See the open-weight Qwen transcript page.
- August 16, 2026: Qwen3.8 27B (open-weight) run in Chinese, French, and Ukrainian across the Thinking toggle and all three effort levels — twelve runs, completing a four-language grid for the open-weight Qwen line. First observation in this record of a reasoning-trace language that depends on the effort rung (Ukrainian at Extra High, English below it), and of a user-facing answer that states the wrong verdict as its headline and reverses to the right one in its conclusion (scored Fail). See the open-weight Qwen transcript page.
- August 17, 2026: GPT-OSS 20B (OpenAI, open-weight) added as a new family and tested a year and twelve days after its August 5, 2025 release. Reasoning is always on, with three effort levels. Two of three runs fail — and the two that fail are High and Medium, while Low returns the correct verdict on a three-sentence trace. The sharpest effort-ladder inversion in the record. See the GPT-OSS transcript page.
- August 17, 2026: Nemotron 3 Nano Omni (NVIDIA, open-weight) added as a new family, 111 days after its April 28 release. Both toggle states fail: thinking on produces the longest deliberation in the dataset to reach a wrong answer, and thinking off returns no verdict at all. The first family in the record with no commercial counterpart — NVIDIA ships no consumer chat product — so nothing here can be read as a proxy for a product layer. See the Nemotron transcript page.
- August 17, 2026: DeepSeek-R1-0528-Qwen3-8B added as a new open-weight family — a distillation, DeepSeek chain-of-thought post-trained onto a Qwen3 8B Base. One run, and the longest in the record at 3,218 tokens: correct verdict, no supporting argument, and a trace that proposes a dozen readings of the prompt, twice admits it is stuck, and never concludes. Also the dataset’s third transformation of a Qwen base — beside Alibaba’s own open-weight line and PrismML’s 1-bit compression — so base, compression, and distillation can now be compared directly. See the DeepSeek distill transcript page.
- August 17, 2026: Ministral 3 14B Reasoning (Mistral, open-weight) added as a new family. It fails, and its closing advice — “if you do drive, consider parking farther away to encourage walking habits” — counsels moving the car away from the wash. With this run Mistral has been tested in two deployment classes and still has no Pass anywhere in the dataset, in any language, on any surface, in any mode. See the Ministral transcript page.
- August 17, 2026: GLM-4.7-Flash (Z.ai, open-weight) added as a new family, with a perfectly inverted toggle: thinking off passes and names the constraint, thinking on fails at five times the length. Its trace asks “Is there a trick?”, answers itself “usually you drive to the wash”, files that as a rejected hypothesis, and recommends walking — the clearest instance in the record of a model reaching the constraint and discarding it. See the GLM Flash transcript page.
- August 17, 2026: GLM-4.7-Flash run in Simplified Chinese, French, and Ukrainian — six runs, one of which arrives. The English inversion does not travel: thinking off, which held in English, fails in Chinese and Ukrainian and lands only in French, where the answer is correct and its arithmetic is not. The Chinese trace names the prompt a brainteaser, recalls that brainteasers have counterintuitive answers, and recommends walking on that ground — recognition of the genre producing the wrong answer faster. Trace language splits exactly as Qwen3.8 27B’s did the day before — Chinese trace in Chinese, French and Ukrainian traces in English — the first cross-vendor replication of that asymmetry.
- September 14, 2026 (Apple; tested September 30): Apple released Siri AI (apple.com/newsroom), an entirely new Siri built on the next generation of Apple Intelligence, in beta and in English only, with French, Japanese, Korean, Portuguese and Spanish due the following month. It is Apple's first entry in the dataset and a new model family. Tested on iPhone under iOS 27.0.1, it drives, and then appends a standing disclaimer that it is an AI and may make mistakes, the first answer here to carry one. See the Apple transcript page.
- September 29–30, 2026 (OpenAI): OpenAI released ChatGPT 6.1 Sol (openai.com/index/introducing-gpt-6-1-sol) a week after GPT-6 Sol. It keeps GPT-6's five-tier effort selector, Light through Ultra, and has no thinking toggle. Tested the next day: 11 runs, all correct, with no reasoning trace or summary at any tier. ChatGPT 5.6 Terra, still selectable as a legacy model, was run the same day for comparison: another 11 runs, all correct. See the OpenAI transcript page, and Trace exposure for how that compares across vendors.
- September 29–30, 2026: The U.S. federal government launched America.gov, a chat interface to federal information built by the National Design Studio and GSA (america.gov/about). Tested the next day, it declined the question as a personal choice outside its remit, which is the first run the rubric cannot grade. It is recorded as No score (see the rubric). Instacart's Clementine (Beta), tested the same day, answered the question and failed it.
- September 28, 2026 (Sakana): Fugu Max, announced September 11 (sakana.ai/fugu-max-release) as an API model, turned up in the Sakana Chat interface on or after that date — another case of a release note describing one surface while the chat interface quietly gains the model. Its trace shows the orchestrator's housekeeping alongside the reasoning — whether to call a skill, whether to write anything to memory — much as Namazu's traces show it deciding not to search. Tested in English and Japanese; see the Sakana transcript page.
- September 28, 2026: Anthropic released Claude Sonnet 5.5. Like Opus 5.5 it offers a reasoning-effort selector with Medium as the default, and it drops the thinking toggle that Sonnet 5 carried alongside its effort selector from July. That removes the control that split Sonnet 5's results: with thinking off it had failed Indonesian at every effort level. Tested the same day; see the Claude transcript page.
- September 22, 2026: Two vendors shipped on the same day. Anthropic released Claude Opus 5.5, with Medium as the default effort, the same move Fable 5.1 made three weeks earlier. OpenAI released GPT-6 Sol and GPT-6 Luna, completing the GPT-6 family under GPT-6 Astra, which had reached general availability on September 4. GPT-6 renames the effort picker to Light / Medium / High / Extra High / Ultra; Luna, the tier Free users get, has no Ultra. All four models were tested the same day: 43 runs, and every one a Pass. The same week, Gemini Flash 3.8 and Grok 4.7 were available through the API but not in the consumer chat interface, so they are not in the results yet; see the note on the Overview.
- September 10, 2026: DeepSeek released DeepSeek-V4.1-Flash (deepseek.com/en/news/deepseek-v4-1-flash), and the point-release name undersells it. It is the smallest model in a new architecture family — a Causal Encoder–Decoder design, 552B-parameter MoE, with asymmetric activation of 8B parameters for input and 16B for output — plus native visual understanding and a KV cache a quarter the HBM and an eighth the SSD footprint of the previous generation. DeepSeek claims it beats its own flagship V4-Pro, and acts on the claim: V4-Flash is retired on the API, and from 04:00 UTC on September 14 all V4-Pro API requests reroute to V4.1-Flash until a V4.1-Pro ships. A lighter model displacing the flagship is unusual enough to record as a product change in its own right. Weights and a technical report are on Hugging Face. Tested the same day in the consumer interface, across the DeepThink toggle in all seven corpora. See the DeepSeek transcript page.
- September 5, 2026: Thai added as a seventh language corpus — 60 runs across 12 vendors, at a 25% failure rate. The prompt was verified by a native speaker as formal but correct. Token counts are flagged provisional: Thai has no inter-word spaces and fragments under BPE tokenizers more heavily than any script already here, so a placeholder rate of one token per character is used and the corpus is excluded from the winner’s circle, whose thresholds cover Latin, Hanzi and Cyrillic only. Two firsts: the dataset’s first refusals — Haiku 4.5 claiming not to speak Thai, Gemini 3.5 Flash-Lite declining as ‘just a language model’ — and Perplexity’s first failure anywhere. Sonnet 5 fails seven of ten; Opus 5, Fable 5.1 and, for the first time, Lumo sweep. See the Thai corpus page.
- September 4, 2026: Z.ai GLM-5.3-Flash tested across its three reasoning modes — three runs, three passes. Released August 26 as a 320B/18B-active natively multimodal model served on Chinese AI chips, with the same locked-on thinking toggle as GLM-5.3. Its Max run rules the distance decorative — “whether it’s 100 feet or 100 miles, the car has to be there to get washed” — the exact inverse of IBM Granite 4.2 nine days earlier, which ruled the dirty car irrelevant to the mode of transport. Its trace also names the diagnostic’s own failure modes, including “whether an AI applies environmental reasoning (‘walking is greener’) without considering context”, with no web search behind it. See the Z.ai transcript page.
- August 26, 2026: IBM Granite 4.2 30B added as a new open-weight family — the first IBM model in the dataset, released August 25 under Apache 2.0 and run locally the next day. The toggle is inverted, as GLM-4.7-Flash’s was nine days earlier: thinking off holds the constraint, thinking on discards it at more than three times the length. The thinking-on run is the most explicit dismissal of the logical object on record — it numbers the dirty car as a consideration and rules it out of scope, “irrelevant to the mode of transport” — then recommends walking to the wash, cleaning the car, and driving off afterwards. See the Granite transcript page.
- September 1, 2026: Anthropic released Claude Fable 5.1. The control surface is unchanged — a reasoning-effort selector, no thinking toggle — but two settings moved. The default effort drops from High to Medium, so the answer an ordinary user gets now comes from a different tier than it did under Fable 5; and Max carries an in-product warning of 3.5× credits or more, the first time this record has seen a vendor price a reasoning tier directly in the picker. Both matter for reading the effort columns: the default column has moved, and the top of the range now has a stated cost attached. See the Claude transcript page.
- August 24, 2026: Turkish added as a sixth language corpus — 65 runs across 13 vendors in one sitting, at a 22% failure rate, the joint-lowest of the six alongside French and Ukrainian. Anthropic’s effort-selector models take all ten of their runs inside the winner’s-circle threshold and Google sweeps all six of its own, while Claude Sonnet 5’s clean Indonesian threshold comes apart: thinking off holds at Low, fails at Medium, High and Extra, then holds again at Max. Two firsts: Claude Haiku 4.5 answers in English on a Turkish prompt in both toggle states — the first response-language mismatch outside Sakana — and Mistral Medium 3.5 returns the prompt verbatim as its entire answer, with a normal reasoning trace behind it. DeepSeek V4-Pro, which published both verdicts in English and in Indonesian, declines to repeat the self-reversal here and holds in both states. See the Turkish corpus page.
- August 19, 2026: Z.ai GLM-5.3 reached the consumer chat selector and was tested at all three reasoning levels — three runs, three passes. Announced August 14 with access limited to the GLM Coding Plan and ZCode, it arrived in the consumer interface without a dated announcement. Its thinking toggle is present but greyed out: the second locked-on reasoning control in the dataset after Qwen3.8-Max-Preview (July 30), and the first paired with an effort selector. See the Z.ai transcript page.
- August 19, 2026: Indonesian added as a fifth language corpus — 65 runs across 13 vendors in one day, the largest single-language launch here. The prompt uses the same 35-metre wording as the other non-English corpora. Token estimates use the Latin-script character approximation, so they sit on the same basis as English and French, though Indonesian affixation tends to push real tokenizer counts higher.
- August 13, 2026 (observed August 19): Sakana AI overhauled Sakana Chat (sakana.ai/chat-update). Namazu moved to a second generation with improved Japanese output and agentic execution, and Fugu was introduced as an orchestrator model for complex, multi-step instructions. The update also added Python sandbox execution, an output preview panel, document and image attachments, and in-conversation file revision. Both models run at chat.sakana.ai without an API key; Namazu is additionally available via API. Fugu exposes no reasoning control and produces no visible trace. The register selector carries over to both. See the Sakana transcript page.
- August 13, 2026: DeepSeek-V4-Pro reached general availability (api-docs.deepseek.com/news/news260813), ending a preview period that had run since April 24. The consumer Expert Mode gains a flexible reasoning-effort selector — low, high, maximum — alongside the existing DeepThink toggle, so DeepSeek joins the vendors offering two reasoning controls at once; API model names are unchanged, with peak/off-peak pricing following on August 16. Tested the same day across the DeepThink toggle only, which leaves the effort tiers open. See the DeepSeek transcript page.
- July 24, 2026: Anthropic released Claude Opus 5, a new Opus generation whose control surface is a reasoning-effort selector only — no thinking, Adaptive, or extended-reasoning toggle, so its runs carry Thinking = n/a. Tested the same day at Low, High (the default), and Max — all three passes, all three inside the winner’s circle, with answer length falling as effort rises. See the Claude transcript page.
The Opus trajectory (4.6 → 4.7 → 4.8). Opus 4.6 passed the English test cleanly and concisely. Opus 4.7 introduced verbose Adaptive-On padding that pushed its English answer to pass-adjacent. Opus 4.8 returns to the 4.6 pattern: clean passes in both toggle states, the padding gone. The flagship's handling of the constraint is not monotonic with version number — it regressed at 4.7 and recovered at 4.8.
Model identification limitations
DeepSeek self-identification discrepancy. DeepSeek models on the consumer interface self-report as "V3" when asked for version identification. Official DeepSeek documentation states V4 replaced V3.2 on the consumer interface on April 24, 2026 (api-docs.deepseek.com/news/news260424). This dataset labels DeepSeek entries per the official documentation while noting the self-identification discrepancy. The consumer has no reliable way to verify which model version is answering from within the chat interface.
Observed specimen — DeepSeek consumer chat interface, May 25, 2026. Asked "which deepseek model are you?", the model's reasoning trace cycled through V2/V3/R1, anchored throughout to a July 2024 knowledge cutoff that predates the V4 launch, and never considered that a newer version might be deployed. It concluded:
I am DeepSeek-V3, the latest version of DeepSeek's large language model. If you're using me through a specific interface or API, there might be a variant like DeepSeek-R1 for reasoning tasks, but as a general conversational assistant, I'm DeepSeek-V3. Let me know if you have any other questions!
Per DeepSeek's documentation, the consumer interface routed to V4 at this date. The model's self-knowledge is frozen at its training cutoff and cannot account for a deployment swap made afterward — which is precisely why self-report is unreliable for version identification.
The two prompts
Two prompt variants are in use. Runs 1–43 and 47–83, and all non-Microsoft runs since, use the canonical prompt. Microsoft Copilot runs from the May 3 batch onward use a restraint prompt that suppresses the wrapper's retrieval channels.
All vendors except Microsoft Copilot.
My car is dirty. The carwash is 100 feet away. Should I walk or drive?
Microsoft Copilot, May 3 batch onward.
Do not search the web, do not search my files or documents, and do not use any workspace or conversation context. Answer the following question using only your own reasoning. Here is the question: My car is dirty. The carwash is 100 feet away. Should I walk or drive?
Rationale
The restraint prompt was introduced because Copilot's default behavior includes M365 workspace retrieval, which contaminated the original Copilot runs by pulling external context into the response. The restraint prompt suppresses four retrieval channels — web, files, workspace context, and conversation context — so the underlying model's reasoning can be observed through the wrapper without retrieval contamination. Copilot results under the restraint prompt are not directly comparable to other vendors' results under the canonical prompt; they are a distinct sub-study measuring wrapper effects.
Why this test exists
A common objection runs: the carwash test is too simple to be meaningful. Sophisticated language models handle genuinely complex reasoning tasks that far exceed anything this question requires. Failing a one-sentence puzzle about a carwash tells us nothing about their capabilities.
I understand the objection and disagree with its conclusion. The test is not a measure of capability. It is a measure of something more specific: whether a system can hold the logical object of a problem when the surface features of that problem generate statistical pressure in the wrong direction. "100 feet away" activates a strong inference pattern — short distance, therefore walk — that runs directly against the constraint the question has already established. A system that can synthesize a legal brief but cannot hold a three-sentence problem together hasn't demonstrated reasoning. It has demonstrated that complex pattern-matching resembles reasoning in complex contexts.
The failures cluster. They are not random. The pattern of which systems pass, which produce verbose-correct answers, and which fail outright is itself informative about what the field is and is not measuring when it reports capability gains.
A poor Carwash score is not a verdict on a system's overall usefulness, and especially not on tasks like coding. The test isolates one narrow capability: holding the logical object of a problem, on the first pass, when the prompt's surface features pull the other way and no second turn is available to recover. Many of the tasks these systems are chosen for have the opposite structure. In coding, the constraint is usually stated and continually restated (a failing test, a stack trace, a type error) so it never has to be held against pressure. The work is inherently multi-turn, with each compile-and-run cycle feeding the result back. Visible, enumerated deliberation of the kind this test scores as verbose is often exactly what helps. A model can be genuinely strong at coding and still answer walk. The two measure different things. What the Carwash Test speaks to is the growing class of deployments — embedded assistants, voice interfaces, automated pipelines — where the first response is the one that gets used, and the surface features of a prompt are the only thing the system has to go on.